
verticapy.machine_learning.vertica.ensemble.RandomForestClassifier
- class verticapy.machine_learning.vertica.ensemble.RandomForestClassifier(name: str = None, overwrite_model: bool = False, n_estimators: int = 10, max_features: Literal['auto', 'max'] | int = 'auto', max_leaf_nodes: Annotated[int | float | Decimal, 'Python Numbers'] = 1000000000.0, sample: float = 0.632, max_depth: int = 5, min_samples_leaf: int = 1, min_info_gain: Annotated[int | float | Decimal, 'Python Numbers'] = 0.0, nbins: int = 32)
Creates a RandomForestClassifier object using the Vertica RF_CLASSIFIER function. It is an ensemble learning method for classification that operates by constructing a multitude of decision trees during training and predicting the class by using a majority voting strategy among the individual trees.
The classifier aggregates the predictions of multiple decision trees to determine the final output class, thus improving the overall prediction accuracy and robustness compared to a single decision tree.
Parameters
- name: str, optional
Name of the model. The model is stored in the DB.
- overwrite_model: bool, optional
If set to
True, training a model with the same name as an existing model overwrites the existing model.- n_estimators: int, optional
The number of trees in the forest, an
integerbetween1and1000, inclusive.- max_features: int | str, optional
The number of randomly chosen features from which to pick the best feature to split a given tree node. It can be an
integeror one of the two following methods.- auto:
square root of the total number of predictors.
- max :
number of predictors.
- max_leaf_nodes: PythonNumber, optional
The maximum number of leaf nodes for a tree in the forest, an
integerv between ``1and1e9, inclusive.- sample: float, optional
The portion of the input data set that is randomly selected for training each tree, a
floatbetween0.0and1.0, inclusive.- max_depth: int, optional
aximum depth of each tree, an
integerbetween1and100, inclusive.- min_samples_leaf: int, optional
The minimum number of samples each branch must have after splitting a node, an
integerbetween1and1e6, inclusive. A split that results in remaining samples less than this value is discarded.- min_info_gain: PythonNumber, optional
The minimum threshold for including a split, a
floatbetween0.0and1.0, inclusive. A split with information gain less than this threshold is discarded.- nbins: int, optional
Number of bins used to find splits in each column, where more splits leads to a longer runtime but more fine-grained, possibly better splits. Must be an
integerbetween2and1000, inclusive.
Attributes
Many attributes are created during the fitting phase.
- trees_: list of BinaryTreeClassifier
Tree models are instances of `
BinaryTreeClassifier, each possessing various attributes. For more detailed information, refer to the documentation forBinaryTreeClassifier.- features_importance_: numpy.array
The importance of features. It is calculated using the MDI (Mean Decreased Impurity). To determine the final score, VerticaPy sums the scores of each tree, normalizes them and applies an activation function to scale them. It is necessary to use the
features_importance()method to compute it initially, and the computed values will be subsequently utilized for subsequent calls.- features_importance_trees_: dict of numpy.array
Each element of the array represents the feature importance of tree i. The importance of features is calculated using the MDI (Mean Decreased Impurity). It is necessary to use the
features_importance()method to compute it initially, and the computed values will be subsequently utilized for subsequent calls.- n_estimators_: int
The number of model estimators.
- classes_: numpy.array
The classes labels.
Note
All attributes can be accessed using the
get_attributes()method.Note
Several other attributes can be accessed by using the
get_vertica_attributes()method.Examples
The following examples provide a basic understanding of usage. For more detailed examples, please refer to the Machine Learning or the Examples section on the website.
Important
Many tree-based models inherit from the
RandomForestbase class, and it’s recommended to use it directly for access to a wider range of options.Load data for machine learning
We import
verticapy:import verticapy as vp
Hint
By assigning an alias to
verticapy, we mitigate the risk of code collisions with other libraries. This precaution is necessary because verticapy uses commonly known function names like “average” and “median”, which can potentially lead to naming conflicts. The use of an alias ensures that the functions fromverticapyare used as intended without interfering with functions from other libraries.For this example, we will use the winequality dataset.
import verticapy.datasets as vpd data = vpd.load_winequality()
 123fixed_acidity123volatile_acidity123citric_acid123residual_sugar123chlorides123free_sulfur_dioxide123total_sulfur_dioxide123density123pH123sulphates123alcohol123quality123goodAbccolor
1 3.9 0.225 0.4 4.2 0.03 29.0 118.0 0.989 3.57 0.36 12.8 8 1 white 2 4.7 0.335 0.14 1.3 0.036 69.0 168.0 0.99212 3.47 0.46 10.5 5 0 white 3 4.7 0.455 0.18 1.9 0.036 33.0 106.0 0.98746 3.21 0.83 14.0 7 1 white 4 4.7 0.785 0.0 3.4 0.036 23.0 134.0 0.98981 3.53 0.92 13.8 6 0 white 5 4.9 0.345 0.34 1.0 0.068 32.0 143.0 0.99138 3.24 0.4 10.1 5 0 white 6 4.9 0.345 0.34 1.0 0.068 32.0 143.0 0.99138 3.24 0.4 10.1 5 0 white 7 4.9 0.42 0.0 2.1 0.048 16.0 42.0 0.99154 3.71 0.74 14.0 7 1 red 8 5.0 0.27 0.4 1.2 0.076 42.0 124.0 0.99204 3.32 0.47 10.1 6 0 white 9 5.0 0.31 0.0 6.4 0.046 43.0 166.0 0.994 3.3 0.63 9.9 6 0 white 10 5.0 0.4 0.5 4.3 0.046 29.0 80.0 0.9902 3.49 0.66 13.6 6 0 red 11 5.0 0.44 0.04 18.6 0.039 38.0 128.0 0.9985 3.37 0.57 10.2 6 0 white 12 5.1 0.11 0.32 1.6 0.028 12.0 90.0 0.99008 3.57 0.52 12.2 6 0 white 13 5.1 0.14 0.25 0.7 0.039 15.0 89.0 0.9919 3.22 0.43 9.2 6 0 white 14 5.1 0.165 0.22 5.7 0.047 42.0 146.0 0.9934 3.18 0.55 9.9 6 0 white 15 5.1 0.33 0.22 1.6 0.027 18.0 89.0 0.9893 3.51 0.38 12.5 7 1 white 16 5.1 0.33 0.22 1.6 0.027 18.0 89.0 0.9893 3.51 0.38 12.5 7 1 white 17 5.1 0.33 0.22 1.6 0.027 18.0 89.0 0.9893 3.51 0.38 12.5 7 1 white 18 5.1 0.39 0.21 1.7 0.027 15.0 72.0 0.9894 3.5 0.45 12.5 6 0 white 19 5.2 0.2 0.27 3.2 0.047 16.0 93.0 0.99235 3.44 0.53 10.1 7 1 white 20 5.2 0.21 0.31 1.7 0.048 17.0 61.0 0.98953 3.24 0.37 12.0 7 1 white 21 5.2 0.22 0.46 6.2 0.066 41.0 187.0 0.99362 3.19 0.42 9.73333333333333 5 0 white 22 5.2 0.31 0.2 2.4 0.027 27.0 117.0 0.98886 3.56 0.45 13.0 7 1 white 23 5.2 0.32 0.25 1.8 0.103 13.0 50.0 0.9957 3.38 0.55 9.2 5 0 red 24 5.2 0.34 0.37 6.2 0.031 42.0 133.0 0.99076 3.25 0.41 12.5 6 0 white 25 5.2 0.36 0.02 1.6 0.031 24.0 104.0 0.9896 3.44 0.35 12.2 6 0 white 26 5.2 0.365 0.08 13.5 0.041 37.0 142.0 0.997 3.46 0.39 9.9 6 0 white 27 5.2 0.48 0.04 1.6 0.054 19.0 106.0 0.9927 3.54 0.62 12.2 7 1 red 28 5.2 0.5 0.18 2.0 0.036 23.0 129.0 0.98949 3.36 0.77 13.4 7 1 white 29 5.3 0.16 0.39 1.0 0.028 40.0 101.0 0.99156 3.57 0.59 10.6 6 0 white 30 5.3 0.16 0.39 1.0 0.028 40.0 101.0 0.99156 3.57 0.59 10.6 6 0 white 31 5.3 0.165 0.24 1.1 0.051 25.0 105.0 0.9925 3.32 0.47 9.1 5 0 white 32 5.3 0.23 0.56 0.9 0.041 46.0 141.0 0.99119 3.16 0.62 9.7 5 0 white 33 5.3 0.3 0.3 1.2 0.029 25.0 93.0 0.98742 3.31 0.4 13.6 7 1 white 34 5.3 0.33 0.3 1.2 0.048 25.0 119.0 0.99045 3.32 0.62 11.3 6 0 white 35 5.3 0.36 0.27 6.3 0.028 40.0 132.0 0.99186 3.37 0.4 11.6 6 0 white 36 5.3 0.36 0.27 6.3 0.028 40.0 132.0 0.99186 3.37 0.4 11.6 6 0 white 37 5.3 0.4 0.25 3.9 0.031 45.0 130.0 0.99072 3.31 0.58 11.75 7 1 white 38 5.3 0.47 0.11 2.2 0.048 16.0 89.0 0.99182 3.54 0.88 13.6 7 1 red 39 5.3 0.47 0.11 2.2 0.048 16.0 89.0 0.99182 3.54 0.88 13.5666666666667 7 1 red 40 5.3 0.715 0.19 1.5 0.161 7.0 62.0 0.99395 3.62 0.61 11.0 5 0 red 41 5.4 0.22 0.29 1.2 0.045 69.0 152.0 0.99178 3.76 0.63 11.0 7 1 white 42 5.4 0.595 0.1 2.8 0.042 26.0 80.0 0.9932 3.36 0.38 9.3 5 0 white 43 5.4 0.74 0.09 1.7 0.089 16.0 26.0 0.99402 3.67 0.56 11.6 6 0 red 44 5.5 0.12 0.33 1.0 0.038 23.0 131.0 0.99164 3.25 0.45 9.8 5 0 white 45 5.5 0.12 0.33 1.0 0.038 23.0 131.0 0.99164 3.25 0.45 9.8 5 0 white 46 5.5 0.14 0.27 4.6 0.029 22.0 104.0 0.9949 3.34 0.44 9.0 5 0 white 47 5.5 0.14 0.27 4.6 0.029 22.0 104.0 0.9949 3.34 0.44 9.0 5 0 white 48 5.5 0.16 0.31 1.2 0.026 31.0 68.0 0.9898 3.33 0.44 11.65 6 0 white 49 5.5 0.16 0.31 1.2 0.026 31.0 68.0 0.9898 3.33 0.44 11.6333333333333 6 0 white 50 5.5 0.18 0.22 5.5 0.037 10.0 86.0 0.99156 3.46 0.44 12.2 5 0 white 51 5.5 0.24 0.45 1.7 0.046 22.0 113.0 0.99224 3.22 0.48 10.0 5 0 white 52 5.5 0.29 0.3 1.1 0.022 20.0 110.0 0.98869 3.34 0.38 12.8 7 1 white 53 5.5 0.31 0.29 3.0 0.027 16.0 102.0 0.99067 3.23 0.56 11.2 6 0 white 54 5.5 0.32 0.45 4.9 0.028 25.0 191.0 0.9922 3.51 0.49 11.5 7 1 white 55 5.5 0.35 0.35 1.1 0.045 14.0 167.0 0.992 3.34 0.68 9.9 6 0 white 56 5.5 0.375 0.38 1.7 0.036 17.0 98.0 0.99142 3.29 0.39 10.5 6 0 white 57 5.6 0.15 0.26 5.55 0.051 51.0 139.0 0.99336 3.47 0.5 11.0 6 0 white 58 5.6 0.15 0.31 5.3 0.038 8.0 79.0 0.9923 3.3 0.39 10.5 6 0 white 59 5.6 0.16 0.27 1.4 0.044 53.0 168.0 0.9918 3.28 0.37 10.1 6 0 white 60 5.6 0.175 0.29 0.8 0.043 20.0 67.0 0.99112 3.28 0.48 9.9 6 0 white 61 5.6 0.185 0.19 7.1 0.048 36.0 110.0 0.99438 3.26 0.41 9.5 6 0 white 62 5.6 0.185 0.19 7.1 0.048 36.0 110.0 0.99438 3.26 0.41 9.5 6 0 white 63 5.6 0.22 0.32 1.2 0.024 29.0 97.0 0.98823 3.2 0.46 13.05 7 1 white 64 5.6 0.26 0.18 1.4 0.034 18.0 135.0 0.99174 3.32 0.35 10.2 6 0 white 65 5.6 0.26 0.26 5.7 0.031 12.0 80.0 0.9923 3.25 0.38 10.8 5 0 white 66 5.6 0.26 0.5 11.4 0.029 25.0 93.0 0.99428 3.23 0.49 10.5 6 0 white 67 5.6 0.28 0.28 4.2 0.044 52.0 158.0 0.992 3.35 0.44 10.7 7 1 white 68 5.6 0.3 0.1 6.4 0.043 34.0 142.0 0.99382 3.14 0.48 9.8 5 0 white 69 5.6 0.35 0.14 5.0 0.046 48.0 198.0 0.9937 3.3 0.71 10.3 5 0 white 70 5.6 0.49 0.13 4.5 0.039 17.0 116.0 0.9907 3.42 0.9 13.7 7 1 white 71 5.6 0.49 0.13 4.5 0.039 17.0 116.0 0.9907 3.42 0.9 13.7 7 1 white 72 5.6 0.66 0.0 2.2 0.087 3.0 11.0 0.99378 3.71 0.63 12.8 7 1 red 73 5.6 0.66 0.0 2.2 0.087 3.0 11.0 0.99378 3.71 0.63 12.8 7 1 red 74 5.7 0.15 0.47 11.4 0.035 49.0 128.0 0.99456 3.03 0.34 10.5 8 1 white 75 5.7 0.18 0.26 2.2 0.023 21.0 95.0 0.9893 3.07 0.54 12.3 6 0 white 76 5.7 0.18 0.36 1.2 0.046 9.0 71.0 0.99199 3.7 0.68 10.9 7 1 white 77 5.7 0.2 0.3 2.5 0.046 38.0 125.0 0.99276 3.34 0.5 9.9 6 0 white 78 5.7 0.21 0.32 0.9 0.038 38.0 121.0 0.99074 3.24 0.46 10.6 6 0 white 79 5.7 0.21 0.37 4.5 0.04 58.0 140.0 0.99332 3.29 0.62 10.6 6 0 white 80 5.7 0.22 0.2 16.0 0.044 41.0 113.0 0.99862 3.22 0.46 8.9 6 0 white 81 5.7 0.22 0.2 16.0 0.044 41.0 113.0 0.99862 3.22 0.46 8.9 6 0 white 82 5.7 0.22 0.2 16.0 0.044 41.0 113.0 0.99862 3.22 0.46 8.9 6 0 white 83 5.7 0.22 0.2 16.0 0.044 41.0 113.0 0.99862 3.22 0.46 8.9 6 0 white 84 5.7 0.22 0.2 16.0 0.044 41.0 113.0 0.99862 3.22 0.46 8.9 6 0 white 85 5.7 0.22 0.29 3.5 0.04 27.0 146.0 0.98999 3.17 0.36 12.1 6 0 white 86 5.7 0.23 0.28 9.65 0.025 26.0 121.0 0.9925 3.28 0.38 11.3 6 0 white 87 5.7 0.25 0.26 12.5 0.049 52.5 106.0 0.99691 3.08 0.45 9.4 6 0 white 88 5.7 0.25 0.26 12.5 0.049 52.5 120.0 0.99691 3.08 0.45 9.4 6 0 white 89 5.7 0.25 0.27 11.5 0.04 24.0 120.0 0.99411 3.33 0.31 10.8 6 0 white 90 5.7 0.26 0.24 17.8 0.059 23.0 124.0 0.99773 3.3 0.5 10.1 5 0 white 91 5.7 0.26 0.24 17.8 0.059 23.0 124.0 0.99773 3.3 0.5 10.1 5 0 white 92 5.7 0.26 0.24 17.8 0.059 23.0 124.0 0.99773 3.3 0.5 10.1 5 0 white 93 5.7 0.27 0.32 1.2 0.046 20.0 155.0 0.9934 3.8 0.41 10.2 6 0 white 94 5.7 0.28 0.24 17.5 0.044 60.0 167.0 0.9989 3.31 0.44 9.4 5 0 white 95 5.7 0.32 0.18 1.4 0.029 26.0 104.0 0.9906 3.44 0.37 11.0 6 0 white 96 5.7 0.32 0.38 4.75 0.033 23.0 94.0 0.991 3.42 0.42 11.8 7 1 white 97 5.7 0.36 0.34 4.2 0.026 21.0 77.0 0.9907 3.41 0.45 11.9 6 0 white 98 5.8 0.14 0.15 6.1 0.042 27.0 123.0 0.99362 3.06 0.6 9.9 6 0 white 99 5.8 0.15 0.32 1.2 0.037 14.0 119.0 0.99137 3.19 0.5 10.2 6 0 white 100 5.8 0.17 0.34 1.8 0.045 96.0 170.0 0.99035 3.38 0.9 11.8 8 1 white Rows: 1-100 | Columns: 14Note
VerticaPy offers a wide range of sample datasets that are ideal for training and testing purposes. You can explore the full list of available datasets in the Datasets, which provides detailed information on each dataset and how to use them effectively. These datasets are invaluable resources for honing your data analysis and machine learning skills within the VerticaPy environment.
You can easily divide your dataset into training and testing subsets using the
vDataFrame.train_test_split()method. This is a crucial step when preparing your data for machine learning, as it allows you to evaluate the performance of your models accurately.data = vpd.load_winequality() train, test = data.train_test_split(test_size = 0.2)
Warning
In this case, VerticaPy utilizes seeded randomization to guarantee the reproducibility of your data split. However, please be aware that this approach may lead to reduced performance. For a more efficient data split, you can use the
vDataFrame.to_db()method to save your results intotablesortemporary tables. This will help enhance the overall performance of the process.Balancing the Dataset
In VerticaPy, balancing a dataset to address class imbalances is made straightforward through the
balance()function within thepreprocessingmodule. This function enables users to rectify skewed class distributions efficiently. By specifying the target variable and setting parameters like the method for balancing, users can effortlessly achieve a more equitable representation of classes in their dataset. Whether opting for over-sampling, under-sampling, or a combination of both, VerticaPy’sbalance()function streamlines the process, empowering users to enhance the performance and fairness of their machine learning models trained on imbalanced data.To balance the dataset, use the following syntax.
from verticapy.machine_learning.vertica.preprocessing import balance balanced_train = balance( name = "my_schema.train_balanced", input_relation = train, y = "good", method = "hybrid", )
Note
With this code, a table named train_balanced is created in the my_schema schema. It can then be used to train the model. In the rest of the example, we will work with the full dataset.
Hint
Balancing the dataset is a crucial step in improving the accuracy of machine learning models, particularly when faced with imbalanced class distributions. By addressing disparities in the number of instances across different classes, the model becomes more adept at learning patterns from all classes rather than being biased towards the majority class. This, in turn, enhances the model’s ability to make accurate predictions for under-represented classes. The balanced dataset ensures that the model is not dominated by the majority class and, as a result, leads to more robust and unbiased model performance. Therefore, by employing techniques such as over-sampling, under-sampling, or a combination of both during dataset preparation, practitioners can significantly contribute to achieving higher accuracy and better generalization of their machine learning models.
Model Initialization
First we import the
RandomForestClassifiermodel:from verticapy.machine_learning.vertica import RandomForestClassifier
Then we can create the model:
model = RandomForestClassifier( max_features = "auto", max_leaf_nodes = 32, sample = 0.5, max_depth = 3, min_samples_leaf = 5, min_info_gain = 0.0, nbins = 32, )
Hint
In
verticapy1.0.x and higher, you do not need to specify the model name, as the name is automatically assigned. If you need to re-use the model, you can fetch the model name from the model’s attributes.Important
The model name is crucial for the model management system and versioning. It’s highly recommended to provide a name if you plan to reuse the model later.
Model Training
We can now fit the model:
model.fit( train, [ "fixed_acidity", "volatile_acidity", "citric_acid", "residual_sugar", "chlorides", "density", ], "good", test, ) =========== call_string =========== SELECT rf_classifier('"public"."_verticapy_tmp_randomforestclassifier_v_mldb_002d6e0c979811efa8720242ac120002_"', '"public"."_verticapy_tmp_view_v_mldb_005d85c4979811efa8720242ac120002_"', 'good', '"fixed_acidity", "volatile_acidity", "citric_acid", "residual_sugar", "chlorides", "density"' USING PARAMETERS exclude_columns='', ntree=10, mtry=3, sampling_size=0.5, max_depth=3, max_breadth=32, min_leaf_size=5, min_info_gain=0, nbins=32); ======= details ======= predictor | type ----------------+---------------- fixed_acidity |float or numeric volatile_acidity|float or numeric citric_acid |float or numeric residual_sugar |float or numeric chlorides |float or numeric density |float or numeric =============== Additional Info =============== Name |Value ------------------+----- tree_count | 10 rejected_row_count| 0 accepted_row_count|5201
Important
To train a model, you can directly use the
vDataFrameor the name of the relation stored in the database. The test set is optional and is only used to compute the test metrics. Inverticapy, we don’t work usingXmatrices andyvectors. Instead, we work directly with lists of predictors and the response name.Features Importance
We can conveniently get the features importance:
result = model.features_importance()
Note
In models such as
RandomForest, feature importance is calculated using the MDI (Mean Decreased Impurity). To determine the final score, VerticaPy sums the scores of each tree, normalizes them and applies an activation function to scale them.Metrics
We can get the entire report using:
model.report()
value auc 0.7861225932074248 prc_auc 0.46152139539418646 accuracy 0.7970679012345679 log_loss 0.185798106186099 precision 0.0 recall 0.0 f1_score 0.0 mcc 0.0 informedness 0.0 markedness -0.20293209876543206 csi 0.0 Rows: 1-11 | Columns: 2Important
Most metrics are computed using a single SQL query, but some of them might require multiple SQL queries. Selecting only the necessary metrics in the report can help optimize performance. E.g.
model.report(metrics = ["auc", "accuracy"]).For classification models, we can easily modify the
cutoffto observe the effect on different metrics:model.report(cutoff = 0.2)
value auc 0.7861225932074248 prc_auc 0.46152139539418646 accuracy 0.7222222222222222 log_loss 0.185798106186099 precision 0.39832285115303984 recall 0.7224334600760456 f1_score 0.5135135135135135 mcc 0.37076455618237414 informedness 0.4446019015087659 markedness 0.30918976201995063 csi 0.34545454545454546 Rows: 1-11 | Columns: 2You can also use the
score()function to compute any classification metric. The default metric is the accuracy:model.score() Out[3]: 0.7970679012345679
Prediction
Prediction is straight-forward:
model.predict( test, [ "fixed_acidity", "volatile_acidity", "citric_acid", "residual_sugar", "chlorides", "density", ], "prediction", )
123fixed_acidity123volatile_acidity123citric_acid123residual_sugar123chlorides123free_sulfur_dioxide123total_sulfur_dioxide123density123pH123sulphates123alcohol123quality123goodAbccolorAbcprediction1 4.8 0.34 0.0 6.5 0.028 33.0 163.0 0.9939 3.36 0.61 9.9 6 0 white 0 2 5.0 0.29 0.54 5.7 0.035 54.0 155.0 0.98976 3.27 0.34 12.9 8 1 white 0 3 5.1 0.25 0.36 1.3 0.035 40.0 78.0 0.9891 3.23 0.64 12.1 7 1 white 0 4 5.1 0.35 0.26 6.8 0.034 36.0 120.0 0.99188 3.38 0.4 11.5 6 0 white 0 5 5.1 0.35 0.26 6.8 0.034 36.0 120.0 0.99188 3.38 0.4 11.5 6 0 white 0 6 5.2 0.185 0.22 1.0 0.03 47.0 123.0 0.99218 3.55 0.44 10.15 6 0 white 0 7 5.2 0.28 0.29 1.1 0.028 18.0 69.0 0.99168 3.24 0.54 10.0 6 0 white 0 8 5.3 0.31 0.38 10.5 0.031 53.0 140.0 0.99321 3.34 0.46 11.7 6 0 white 0 9 5.3 0.58 0.07 6.9 0.043 34.0 149.0 0.9944 3.34 0.57 9.7 5 0 white 0 10 5.4 0.18 0.24 4.8 0.041 30.0 113.0 0.99445 3.42 0.4 9.4 6 0 white 0 11 5.4 0.205 0.16 12.55 0.051 31.0 115.0 0.99564 3.4 0.38 10.8 6 0 white 0 12 5.4 0.29 0.38 1.2 0.029 31.0 132.0 0.98895 3.28 0.36 12.4 6 0 white 0 13 5.6 0.19 0.46 1.1 0.032 33.0 115.0 0.9909 3.36 0.5 10.4 6 0 white 0 14 5.6 0.23 0.29 3.1 0.023 19.0 89.0 0.99068 3.25 0.51 11.2 6 0 white 0 15 5.6 0.28 0.27 3.9 0.043 52.0 158.0 0.99202 3.35 0.44 10.7 7 1 white 0 16 5.6 0.33 0.28 1.2 0.031 33.0 97.0 0.99126 3.49 0.58 10.9 6 0 white 0 17 5.6 0.34 0.1 1.3 0.031 20.0 68.0 0.9906 3.36 0.51 11.2 7 1 white 0 18 5.7 0.14 0.3 5.4 0.045 26.0 105.0 0.99469 3.32 0.45 9.3 5 0 white 0 19 5.7 0.22 0.22 16.65 0.044 39.0 110.0 0.99855 3.24 0.48 9.0 6 0 white 0 20 5.7 0.22 0.22 16.65 0.044 39.0 110.0 0.99855 3.24 0.48 9.0 6 0 white 0 21 5.7 0.22 0.22 16.65 0.044 39.0 110.0 0.99855 3.24 0.48 9.0 6 0 white 0 22 5.7 0.255 0.65 1.2 0.079 17.0 137.0 0.99307 3.2 0.42 9.4 5 0 white 0 23 5.8 0.19 0.25 10.8 0.042 33.0 124.0 0.99646 3.22 0.41 9.2 6 0 white 0 24 5.8 0.2 0.24 1.4 0.033 65.0 169.0 0.99043 3.59 0.56 12.3 7 1 white 0 25 5.8 0.25 0.28 11.1 0.056 45.0 175.0 0.99755 3.42 0.43 9.5 5 0 white 0 26 5.8 0.26 0.24 9.2 0.044 55.0 152.0 0.9961 3.31 0.38 9.4 5 0 white 0 27 5.8 0.27 0.26 3.5 0.071 26.0 69.0 0.98994 3.1 0.38 11.5 6 0 white 0 28 5.8 0.27 0.27 12.3 0.045 55.0 170.0 0.9972 3.28 0.42 9.3 6 0 white 0 29 5.8 0.315 0.27 1.55 0.026 15.0 70.0 0.98994 3.37 0.4 11.9 8 1 white 0 30 5.8 0.34 0.16 7.0 0.037 26.0 116.0 0.9949 3.46 0.45 10.0 7 1 white 0 31 5.8 0.36 0.26 3.3 0.038 40.0 153.0 0.9911 3.34 0.55 11.3 6 0 white 0 32 5.8 0.36 0.5 1.0 0.127 63.0 178.0 0.99212 3.1 0.45 9.7 5 0 white 0 33 5.8 0.38 0.26 1.1 0.058 20.0 140.0 0.99271 3.27 0.43 9.7 6 0 white 0 34 5.9 0.17 0.28 0.7 0.027 5.0 28.0 0.98985 3.13 0.32 10.6 5 0 white 0 35 5.9 0.17 0.29 3.1 0.03 32.0 123.0 0.98913 3.41 0.33 13.7 7 1 white 0 36 5.9 0.2 0.23 1.5 0.037 38.0 93.0 0.99021 3.36 0.49 12.0 6 0 white 0 37 5.9 0.25 0.19 12.4 0.047 50.0 162.0 0.9973 3.35 0.38 9.5 5 0 white 0 38 5.9 0.27 0.27 9.0 0.051 43.0 136.0 0.9941 3.25 0.53 10.7 6 0 white 0 39 5.9 0.28 0.34 3.6 0.04 50.0 194.0 0.9912 3.31 0.52 11.6 6 0 white 0 40 5.9 0.29 0.25 13.4 0.067 72.0 160.0 0.99721 3.33 0.54 10.3 6 0 red 0 41 5.9 0.35 0.47 2.2 0.11 14.0 138.0 0.9932 3.09 0.5 9.1 5 0 white 0 42 5.9 0.36 0.04 5.7 0.046 21.0 87.0 0.9934 3.22 0.51 10.2 5 0 white 0 43 5.9 0.65 0.23 5.0 0.035 20.0 128.0 0.99016 3.46 0.48 12.8 6 0 white 0 44 6.0 0.2 0.71 1.6 0.15 10.0 54.0 0.9927 3.12 0.47 9.8 5 0 white 0 45 6.0 0.24 0.27 1.9 0.048 40.0 170.0 0.9938 3.64 0.54 10.0 7 1 white 0 46 6.0 0.26 0.15 1.2 0.053 35.0 124.0 0.99347 3.08 0.46 8.8 5 0 white 0 47 6.0 0.26 0.18 7.0 0.055 50.0 194.0 0.99591 3.21 0.43 9.0 5 0 white 0 48 6.0 0.26 0.26 2.2 0.035 10.0 72.0 0.989465 3.11 0.48 12.15 6 0 white 0 49 6.0 0.27 0.32 3.6 0.035 36.0 133.0 0.99215 3.23 0.46 10.8 6 0 white 0 50 6.0 0.28 0.24 17.8 0.047 42.0 111.0 0.99896 3.1 0.45 8.9 6 0 white 0 51 6.0 0.28 0.24 17.8 0.047 42.0 111.0 0.99896 3.1 0.45 8.9 6 0 white 0 52 6.0 0.28 0.52 6.2 0.028 37.0 104.0 0.99161 3.28 0.51 11.8 7 1 white 0 53 6.0 0.32 0.3 1.9 0.033 41.0 142.0 0.98912 3.29 0.42 12.8 7 1 white 0 54 6.0 0.36 0.39 3.2 0.027 20.0 125.0 0.991 3.38 0.39 11.3 7 1 white 0 55 6.0 0.42 0.19 2.0 0.075 22.0 47.0 0.99522 3.39 0.78 10.0 6 0 red 0 56 6.0 0.45 0.42 1.1 0.051 61.0 197.0 0.9932 3.02 0.4 9.0 5 0 white 0 57 6.0 0.49 0.0 2.3 0.068 15.0 33.0 0.99292 3.58 0.59 12.5 6 0 red 0 58 6.0 0.58 0.2 2.4 0.075 15.0 50.0 0.99467 3.58 0.67 12.5 6 0 red 0 59 6.0 0.615 0.04 0.8 0.032 8.0 50.0 0.99036 3.14 0.4 11.0 4 0 white 0 60 6.1 0.28 0.24 19.95 0.074 32.0 174.0 0.99922 3.19 0.44 9.3 6 0 white 0 61 6.1 0.3 0.56 2.8 0.044 47.0 179.0 0.9924 3.3 0.57 10.9 7 1 white 0 62 6.1 0.32 0.25 1.8 0.086 5.0 32.0 0.99464 3.36 0.44 10.1 5 0 red 0 63 6.1 0.32 0.28 6.6 0.021 29.0 132.0 0.99188 3.15 0.36 11.45 7 1 white 0 64 6.1 0.34 0.24 18.35 0.05 33.0 184.0 0.99943 3.12 0.61 9.3 5 0 white 0 65 6.1 0.4 0.16 1.8 0.069 11.0 25.0 0.9955 3.42 0.74 10.1 7 1 red 0 66 6.1 0.41 0.14 10.4 0.037 18.0 119.0 0.996 3.38 0.45 10.0 5 0 white 0 67 6.1 0.44 0.28 4.25 0.032 43.0 132.0 0.9916 3.26 0.47 11.3 7 1 white 0 68 6.2 0.16 0.54 1.4 0.126 37.0 110.0 0.9932 3.23 0.37 8.9 6 0 white 0 69 6.2 0.2 0.31 1.0 0.031 22.0 73.0 0.99035 3.24 0.52 11.3 6 0 white 0 70 6.2 0.2 0.33 5.4 0.028 21.0 75.0 0.99012 3.36 0.41 13.5 7 1 white 0 71 6.2 0.22 0.2 20.8 0.035 58.0 184.0 1.00022 3.11 0.53 9.0 6 0 white 0 72 6.2 0.22 0.28 2.2 0.04 24.0 125.0 0.9917 3.19 0.48 10.5 6 0 white 0 73 6.2 0.22 0.28 2.2 0.04 24.0 125.0 0.9917 3.19 0.48 10.5 6 0 white 0 74 6.2 0.23 0.38 1.6 0.044 12.0 113.0 0.99176 3.3 0.73 11.4 5 0 white 0 75 6.2 0.25 0.44 15.8 0.057 39.0 167.0 0.99804 3.14 0.51 9.2 5 0 white 0 76 6.2 0.27 0.32 6.3 0.048 47.0 159.0 0.99282 3.21 0.6 11.0 6 0 white 0 77 6.2 0.3 0.21 1.1 0.032 31.0 111.0 0.9889 2.97 0.42 12.2 6 0 white 0 78 6.2 0.31 0.21 6.3 0.041 50.0 218.0 0.9941 3.15 0.6 10.0 5 0 white 0 79 6.2 0.33 0.29 1.3 0.042 26.0 138.0 0.9956 3.77 0.64 9.5 5 0 white 0 80 6.2 0.35 0.31 2.6 0.036 37.0 92.0 0.98938 3.27 0.53 12.8 7 1 white 0 81 6.2 0.37 0.24 6.1 0.032 19.0 86.0 0.98934 3.04 0.26 13.4 8 1 white 0 82 6.2 0.37 0.24 6.1 0.032 19.0 86.0 0.98934 3.04 0.26 13.4 8 1 white 0 83 6.2 0.37 0.3 6.6 0.346 79.0 200.0 0.9954 3.29 0.58 9.6 5 0 white 0 84 6.2 0.46 0.25 4.4 0.066 62.0 207.0 0.9939 3.25 0.52 9.8 5 0 white 0 85 6.2 0.46 0.29 2.1 0.074 32.0 98.0 0.99578 3.33 0.62 9.8 5 0 red 0 86 6.2 0.58 0.0 1.6 0.065 8.0 18.0 0.9966 3.56 0.84 9.4 5 0 red 0 87 6.2 0.63 0.31 1.7 0.088 15.0 64.0 0.9969 3.46 0.79 9.3 5 0 red 0 88 6.3 0.15 0.34 11.4 0.05 25.0 96.0 0.99754 3.21 0.49 10.0 6 0 white 0 89 6.3 0.23 0.3 1.8 0.033 16.0 91.0 0.9906 3.28 0.4 11.8 6 0 white 0 90 6.3 0.23 0.49 7.1 0.05 67.0 210.0 0.9951 3.23 0.34 9.5 5 0 white 0 91 6.3 0.26 0.29 2.2 0.043 35.0 175.0 0.9918 3.38 0.43 11.6 6 0 white 0 92 6.3 0.27 0.18 7.7 0.048 45.0 186.0 0.9962 3.23 0.47 9.0 5 0 white 0 93 6.3 0.27 0.23 2.9 0.047 13.0 100.0 0.9936 3.28 0.43 9.8 5 0 white 0 94 6.3 0.32 0.35 11.1 0.039 29.0 198.0 0.9984 3.36 0.5 9.4 7 1 white 0 95 6.3 0.33 0.2 17.9 0.066 36.0 161.0 0.9991 3.14 0.51 8.8 5 0 white 0 96 6.3 0.37 0.37 1.5 0.024 12.0 76.0 0.98876 2.94 0.39 12.3 6 0 white 0 97 6.3 0.41 0.33 4.7 0.023 28.0 110.0 0.991 3.3 0.38 12.5 7 1 white 0 98 6.3 1.02 0.0 2.0 0.083 17.0 24.0 0.99437 3.59 0.55 11.2 4 0 red 0 99 6.4 0.15 0.29 1.8 0.044 21.0 115.0 0.99166 3.1 0.38 10.2 5 0 white 0 100 6.4 0.15 0.31 1.1 0.044 25.0 96.0 0.9932 3.54 0.51 10.3 6 0 white 0 Rows: 1-100 | Columns: 15Note
Predictions can be made automatically using the test set, in which case you don’t need to specify the predictors. Alternatively, you can pass only the
vDataFrameto thepredict()function, but in this case, it’s essential that the column names of thevDataFramematch the predictors and response name in the model.Probabilities
It is also easy to get the model’s probabilities:
model.predict_proba( test, [ "fixed_acidity", "volatile_acidity", "citric_acid", "residual_sugar", "chlorides", "density", ], "prediction", )
123fixed_acidity123volatile_acidity123citric_acid123residual_sugar123chlorides123free_sulfur_dioxide123total_sulfur_dioxide123density123pH123sulphates123alcohol123quality123goodAbccolorAbcpredictionAbcprediction_0Abcprediction_11 4.8 0.34 0.0 6.5 0.028 33.0 163.0 0.9939 3.36 0.61 9.9 6 0 white 0 0.898569 0.101431 2 5.0 0.29 0.54 5.7 0.035 54.0 155.0 0.98976 3.27 0.34 12.9 8 1 white 0 0.585182 0.414818 3 5.1 0.25 0.36 1.3 0.035 40.0 78.0 0.9891 3.23 0.64 12.1 7 1 white 0 0.630081 0.369919 4 5.1 0.35 0.26 6.8 0.034 36.0 120.0 0.99188 3.38 0.4 11.5 6 0 white 0 0.603775 0.396225 5 5.1 0.35 0.26 6.8 0.034 36.0 120.0 0.99188 3.38 0.4 11.5 6 0 white 0 0.603775 0.396225 6 5.2 0.185 0.22 1.0 0.03 47.0 123.0 0.99218 3.55 0.44 10.15 6 0 white 0 0.758513 0.241487 7 5.2 0.28 0.29 1.1 0.028 18.0 69.0 0.99168 3.24 0.54 10.0 6 0 white 0 0.722039 0.277961 8 5.3 0.31 0.38 10.5 0.031 53.0 140.0 0.99321 3.34 0.46 11.7 6 0 white 0 0.845468 0.154532 9 5.3 0.58 0.07 6.9 0.043 34.0 149.0 0.9944 3.34 0.57 9.7 5 0 white 0 0.895263 0.104737 10 5.4 0.18 0.24 4.8 0.041 30.0 113.0 0.99445 3.42 0.4 9.4 6 0 white 0 0.836464 0.163536 11 5.4 0.205 0.16 12.55 0.051 31.0 115.0 0.99564 3.4 0.38 10.8 6 0 white 0 0.890809 0.109191 12 5.4 0.29 0.38 1.2 0.029 31.0 132.0 0.98895 3.28 0.36 12.4 6 0 white 0 0.630081 0.369919 13 5.6 0.19 0.46 1.1 0.032 33.0 115.0 0.9909 3.36 0.5 10.4 6 0 white 0 0.643849 0.356151 14 5.6 0.23 0.29 3.1 0.023 19.0 89.0 0.99068 3.25 0.51 11.2 6 0 white 0 0.529253 0.470747 15 5.6 0.28 0.27 3.9 0.043 52.0 158.0 0.99202 3.35 0.44 10.7 7 1 white 0 0.617696 0.382304 16 5.6 0.33 0.28 1.2 0.031 33.0 97.0 0.99126 3.49 0.58 10.9 6 0 white 0 0.614657 0.385343 17 5.6 0.34 0.1 1.3 0.031 20.0 68.0 0.9906 3.36 0.51 11.2 7 1 white 0 0.618969 0.381031 18 5.7 0.14 0.3 5.4 0.045 26.0 105.0 0.99469 3.32 0.45 9.3 5 0 white 0 0.828846 0.171154 19 5.7 0.22 0.22 16.65 0.044 39.0 110.0 0.99855 3.24 0.48 9.0 6 0 white 0 0.863451 0.136549 20 5.7 0.22 0.22 16.65 0.044 39.0 110.0 0.99855 3.24 0.48 9.0 6 0 white 0 0.863451 0.136549 21 5.7 0.22 0.22 16.65 0.044 39.0 110.0 0.99855 3.24 0.48 9.0 6 0 white 0 0.863451 0.136549 22 5.7 0.255 0.65 1.2 0.079 17.0 137.0 0.99307 3.2 0.42 9.4 5 0 white 0 0.862273 0.137727 23 5.8 0.19 0.25 10.8 0.042 33.0 124.0 0.99646 3.22 0.41 9.2 6 0 white 0 0.863451 0.136549 24 5.8 0.2 0.24 1.4 0.033 65.0 169.0 0.99043 3.59 0.56 12.3 7 1 white 0 0.611036 0.388964 25 5.8 0.25 0.28 11.1 0.056 45.0 175.0 0.99755 3.42 0.43 9.5 5 0 white 0 0.884316 0.115684 26 5.8 0.26 0.24 9.2 0.044 55.0 152.0 0.9961 3.31 0.38 9.4 5 0 white 0 0.898569 0.101431 27 5.8 0.27 0.26 3.5 0.071 26.0 69.0 0.98994 3.1 0.38 11.5 6 0 white 0 0.751833 0.248167 28 5.8 0.27 0.27 12.3 0.045 55.0 170.0 0.9972 3.28 0.42 9.3 6 0 white 0 0.868822 0.131178 29 5.8 0.315 0.27 1.55 0.026 15.0 70.0 0.98994 3.37 0.4 11.9 8 1 white 0 0.584251 0.415749 30 5.8 0.34 0.16 7.0 0.037 26.0 116.0 0.9949 3.46 0.45 10.0 7 1 white 0 0.898569 0.101431 31 5.8 0.36 0.26 3.3 0.038 40.0 153.0 0.9911 3.34 0.55 11.3 6 0 white 0 0.545069 0.454931 32 5.8 0.36 0.5 1.0 0.127 63.0 178.0 0.99212 3.1 0.45 9.7 5 0 white 0 0.841109 0.158891 33 5.8 0.38 0.26 1.1 0.058 20.0 140.0 0.99271 3.27 0.43 9.7 6 0 white 0 0.879365 0.120635 34 5.9 0.17 0.28 0.7 0.027 5.0 28.0 0.98985 3.13 0.32 10.6 5 0 white 0 0.598842 0.401158 35 5.9 0.17 0.29 3.1 0.03 32.0 123.0 0.98913 3.41 0.33 13.7 7 1 white 0 0.545891 0.454109 36 5.9 0.2 0.23 1.5 0.037 38.0 93.0 0.99021 3.36 0.49 12.0 6 0 white 0 0.611036 0.388964 37 5.9 0.25 0.19 12.4 0.047 50.0 162.0 0.9973 3.35 0.38 9.5 5 0 white 0 0.941882 0.0581183 38 5.9 0.27 0.27 9.0 0.051 43.0 136.0 0.9941 3.25 0.53 10.7 6 0 white 0 0.884316 0.115684 39 5.9 0.28 0.34 3.6 0.04 50.0 194.0 0.9912 3.31 0.52 11.6 6 0 white 0 0.559361 0.440639 40 5.9 0.29 0.25 13.4 0.067 72.0 160.0 0.99721 3.33 0.54 10.3 6 0 red 0 0.941882 0.0581183 41 5.9 0.35 0.47 2.2 0.11 14.0 138.0 0.9932 3.09 0.5 9.1 5 0 white 0 0.862273 0.137727 42 5.9 0.36 0.04 5.7 0.046 21.0 87.0 0.9934 3.22 0.51 10.2 5 0 white 0 0.877653 0.122347 43 5.9 0.65 0.23 5.0 0.035 20.0 128.0 0.99016 3.46 0.48 12.8 6 0 white 0 0.529936 0.470064 44 6.0 0.2 0.71 1.6 0.15 10.0 54.0 0.9927 3.12 0.47 9.8 5 0 white 0 0.868329 0.131671 45 6.0 0.24 0.27 1.9 0.048 40.0 170.0 0.9938 3.64 0.54 10.0 7 1 white 0 0.884316 0.115684 46 6.0 0.26 0.15 1.2 0.053 35.0 124.0 0.99347 3.08 0.46 8.8 5 0 white 0 0.924899 0.0751014 47 6.0 0.26 0.18 7.0 0.055 50.0 194.0 0.99591 3.21 0.43 9.0 5 0 white 0 0.935018 0.0649818 48 6.0 0.26 0.26 2.2 0.035 10.0 72.0 0.989465 3.11 0.48 12.15 6 0 white 0 0.545891 0.454109 49 6.0 0.27 0.32 3.6 0.035 36.0 133.0 0.99215 3.23 0.46 10.8 6 0 white 0 0.617696 0.382304 50 6.0 0.28 0.24 17.8 0.047 42.0 111.0 0.99896 3.1 0.45 8.9 6 0 white 0 0.941882 0.0581183 51 6.0 0.28 0.24 17.8 0.047 42.0 111.0 0.99896 3.1 0.45 8.9 6 0 white 0 0.941882 0.0581183 52 6.0 0.28 0.52 6.2 0.028 37.0 104.0 0.99161 3.28 0.51 11.8 7 1 white 0 0.617696 0.382304 53 6.0 0.32 0.3 1.9 0.033 41.0 142.0 0.98912 3.29 0.42 12.8 7 1 white 0 0.531301 0.468699 54 6.0 0.36 0.39 3.2 0.027 20.0 125.0 0.991 3.38 0.39 11.3 7 1 white 0 0.543031 0.456969 55 6.0 0.42 0.19 2.0 0.075 22.0 47.0 0.99522 3.39 0.78 10.0 6 0 red 0 0.929849 0.0701507 56 6.0 0.45 0.42 1.1 0.051 61.0 197.0 0.9932 3.02 0.4 9.0 5 0 white 0 0.872502 0.127498 57 6.0 0.49 0.0 2.3 0.068 15.0 33.0 0.99292 3.58 0.59 12.5 6 0 red 0 0.924899 0.0751014 58 6.0 0.58 0.2 2.4 0.075 15.0 50.0 0.99467 3.58 0.67 12.5 6 0 red 0 0.937275 0.0627251 59 6.0 0.615 0.04 0.8 0.032 8.0 50.0 0.99036 3.14 0.4 11.0 4 0 white 0 0.636947 0.363053 60 6.1 0.28 0.24 19.95 0.074 32.0 174.0 0.99922 3.19 0.44 9.3 6 0 white 0 0.941882 0.0581183 61 6.1 0.3 0.56 2.8 0.044 47.0 179.0 0.9924 3.3 0.57 10.9 7 1 white 0 0.798119 0.201881 62 6.1 0.32 0.25 1.8 0.086 5.0 32.0 0.99464 3.36 0.44 10.1 5 0 red 0 0.929849 0.0701507 63 6.1 0.32 0.28 6.6 0.021 29.0 132.0 0.99188 3.15 0.36 11.45 7 1 white 0 0.587137 0.412863 64 6.1 0.34 0.24 18.35 0.05 33.0 184.0 0.99943 3.12 0.61 9.3 5 0 white 0 0.941882 0.0581183 65 6.1 0.4 0.16 1.8 0.069 11.0 25.0 0.9955 3.42 0.74 10.1 7 1 red 0 0.929849 0.0701507 66 6.1 0.41 0.14 10.4 0.037 18.0 119.0 0.996 3.38 0.45 10.0 5 0 white 0 0.909591 0.0904091 67 6.1 0.44 0.28 4.25 0.032 43.0 132.0 0.9916 3.26 0.47 11.3 7 1 white 0 0.603105 0.396895 68 6.2 0.16 0.54 1.4 0.126 37.0 110.0 0.9932 3.23 0.37 8.9 6 0 white 0 0.820954 0.179046 69 6.2 0.2 0.31 1.0 0.031 22.0 73.0 0.99035 3.24 0.52 11.3 6 0 white 0 0.61548 0.38452 70 6.2 0.2 0.33 5.4 0.028 21.0 75.0 0.99012 3.36 0.41 13.5 7 1 white 0 0.545593 0.454407 71 6.2 0.22 0.2 20.8 0.035 58.0 184.0 1.00022 3.11 0.53 9.0 6 0 white 0 0.84472 0.15528 72 6.2 0.22 0.28 2.2 0.04 24.0 125.0 0.9917 3.19 0.48 10.5 6 0 white 0 0.65251 0.34749 73 6.2 0.22 0.28 2.2 0.04 24.0 125.0 0.9917 3.19 0.48 10.5 6 0 white 0 0.65251 0.34749 74 6.2 0.23 0.38 1.6 0.044 12.0 113.0 0.99176 3.3 0.73 11.4 5 0 white 0 0.65251 0.34749 75 6.2 0.25 0.44 15.8 0.057 39.0 167.0 0.99804 3.14 0.51 9.2 5 0 white 0 0.875876 0.124124 76 6.2 0.27 0.32 6.3 0.048 47.0 159.0 0.99282 3.21 0.6 11.0 6 0 white 0 0.850255 0.149745 77 6.2 0.3 0.21 1.1 0.032 31.0 111.0 0.9889 2.97 0.42 12.2 6 0 white 0 0.611036 0.388964 78 6.2 0.31 0.21 6.3 0.041 50.0 218.0 0.9941 3.15 0.6 10.0 5 0 white 0 0.882604 0.117396 79 6.2 0.33 0.29 1.3 0.042 26.0 138.0 0.9956 3.77 0.64 9.5 5 0 white 0 0.857129 0.142871 80 6.2 0.35 0.31 2.6 0.036 37.0 92.0 0.98938 3.27 0.53 12.8 7 1 white 0 0.531301 0.468699 81 6.2 0.37 0.24 6.1 0.032 19.0 86.0 0.98934 3.04 0.26 13.4 8 1 white 0 0.511958 0.488042 82 6.2 0.37 0.24 6.1 0.032 19.0 86.0 0.98934 3.04 0.26 13.4 8 1 white 0 0.511958 0.488042 83 6.2 0.37 0.3 6.6 0.346 79.0 200.0 0.9954 3.29 0.58 9.6 5 0 white 0 0.884316 0.115684 84 6.2 0.46 0.25 4.4 0.066 62.0 207.0 0.9939 3.25 0.52 9.8 5 0 white 0 0.935018 0.0649818 85 6.2 0.46 0.29 2.1 0.074 32.0 98.0 0.99578 3.33 0.62 9.8 5 0 red 0 0.894544 0.105456 86 6.2 0.58 0.0 1.6 0.065 8.0 18.0 0.9966 3.56 0.84 9.4 5 0 red 0 0.920055 0.0799455 87 6.2 0.63 0.31 1.7 0.088 15.0 64.0 0.9969 3.46 0.79 9.3 5 0 red 0 0.901969 0.0980305 88 6.3 0.15 0.34 11.4 0.05 25.0 96.0 0.99754 3.21 0.49 10.0 6 0 white 0 0.813956 0.186044 89 6.3 0.23 0.3 1.8 0.033 16.0 91.0 0.9906 3.28 0.4 11.8 6 0 white 0 0.545891 0.454109 90 6.3 0.23 0.49 7.1 0.05 67.0 210.0 0.9951 3.23 0.34 9.5 5 0 white 0 0.867224 0.132776 91 6.3 0.26 0.29 2.2 0.043 35.0 175.0 0.9918 3.38 0.43 11.6 6 0 white 0 0.65251 0.34749 92 6.3 0.27 0.18 7.7 0.048 45.0 186.0 0.9962 3.23 0.47 9.0 5 0 white 0 0.935018 0.0649818 93 6.3 0.27 0.23 2.9 0.047 13.0 100.0 0.9936 3.28 0.43 9.8 5 0 white 0 0.918049 0.0819509 94 6.3 0.32 0.35 11.1 0.039 29.0 198.0 0.9984 3.36 0.5 9.4 7 1 white 0 0.868822 0.131178 95 6.3 0.33 0.2 17.9 0.066 36.0 161.0 0.9991 3.14 0.51 8.8 5 0 white 0 0.941882 0.0581183 96 6.3 0.37 0.37 1.5 0.024 12.0 76.0 0.98876 2.94 0.39 12.3 6 0 white 0 0.598851 0.401149 97 6.3 0.41 0.33 4.7 0.023 28.0 110.0 0.991 3.3 0.38 12.5 7 1 white 0 0.528132 0.471868 98 6.3 1.02 0.0 2.0 0.083 17.0 24.0 0.99437 3.59 0.55 11.2 4 0 red 0 0.937275 0.0627251 99 6.4 0.15 0.29 1.8 0.044 21.0 115.0 0.99166 3.1 0.38 10.2 5 0 white 0 0.65251 0.34749 100 6.4 0.15 0.31 1.1 0.044 25.0 96.0 0.9932 3.54 0.51 10.3 6 0 white 0 0.793147 0.206853 Rows: 1-100 | Columns: 17Note
Probabilities are added to the
vDataFrame, and VerticaPy uses the corresponding probability function in SQL behind the scenes. You can use thepos_labelparameter to add only the probability of the selected category.Confusion Matrix
You can obtain the confusion matrix of your choice by specifying the desired cutoff.
model.confusion_matrix(cutoff = 0.5) Out[4]: array([[1033, 0], [ 263, 0]])
Note
In classification, the
cutoffis a threshold value used to determine class assignment based on predicted probabilities or scores from a classification model. In binary classification, if the predicted probability for a specific class is greater than or equal to the cutoff, the instance is assigned to the positive class; otherwise, it is assigned to the negative class. Adjusting the cutoff allows for trade-offs between true positives and false positives, enabling the model to be optimized for specific objectives or to consider the relative costs of different classification errors. The choice of cutoff is critical for tailoring the model’s performance to meet specific needs.Main Plots (Classification Curves)
Classification models allow for the creation of various plots that are very helpful in understanding the model, such as the ROC Curve, PRC Curve, Cutoff Curve, Gain Curve, and more.
Most of the classification curves can be found in the Machine Learning - Classification Curve.
For example, let’s draw the model’s ROC curve.
model.roc_curve()
Important
Most of the curves have a parameter called
nbins, which is essential for estimating metrics. The larger thenbins, the more precise the estimation, but it can significantly impact performance. Exercise caution when increasing this parameter excessively.Hint
In binary classification, various curves can be easily plotted. However, in multi-class classification, it’s important to select the
pos_label, representing the class to be treated as positive when drawing the curve.Other Plots
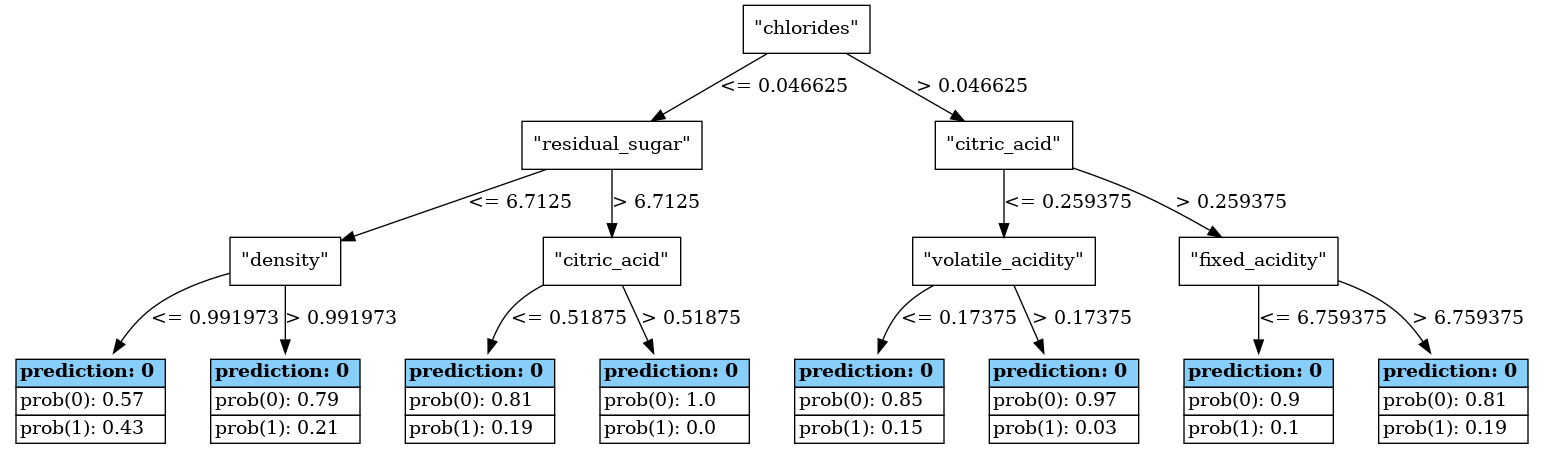
Tree models can be visualized by drawing their tree plots. For more examples, check out Machine Learning - Tree Plots.
model.plot_tree()
Note
The above example may not render properly in the doc because of the huge size of the tree. But it should render nicely in jupyter environment.
In order to plot graph using graphviz separately, you can extract the graphviz DOT file code as follows:
model.to_graphviz() Out[5]: 'digraph Tree {\ngraph [bgcolor="#FFFFFFDD"];\n0 [label="\\"density\\"", shape="box", style="filled", fillcolor="#FFFFFFDD", fontcolor="#000000", color="#000000"]\n0 -> 1 [label="<= 0.992198", color="#000000", fontcolor="#000000"]\n0 -> 2 [label="> 0.992198", color="#000000", fontcolor="#000000"]\n1 [label="\\"residual_sugar\\"", shape="box", style="filled", fillcolor="#FFFFFFDD", fontcolor="#000000", color="#000000"]\n1 -> 3 [label="<= 1.56875", color="#000000", fontcolor="#000000"]\n1 -> 4 [label="> 1.56875", color="#000000", fontcolor="#000000"]\n2 [label="\\"volatile_acidity\\"", shape="box", style="filled", fillcolor="#FFFFFFDD", fontcolor="#000000", color="#000000"]\n2 -> 5 [label="<= 0.220625", color="#000000", fontcolor="#000000"]\n2 -> 6 [label="> 0.220625", color="#000000", fontcolor="#000000"]\n3 [label="\\"density\\"", shape="box", style="filled", fillcolor="#FFFFFFDD", fontcolor="#000000", color="#000000"]\n3 -> 7 [label="<= 0.991474", color="#000000", fontcolor="#000000"]\n3 -> 8 [label="> 0.991474", color="#000000", fontcolor="#000000"]\n4 [label="\\"chlorides\\"", shape="box", style="filled", fillcolor="#FFFFFFDD", fontcolor="#000000", color="#000000"]\n4 -> 9 [label="<= 0.046625", color="#000000", fontcolor="#000000"]\n4 -> 10 [label="> 0.046625", color="#000000", fontcolor="#000000"]\n5 [label="\\"fixed_acidity\\"", shape="box", style="filled", fillcolor="#FFFFFFDD", fontcolor="#000000", color="#000000"]\n5 -> 11 [label="<= 6.15", color="#000000", fontcolor="#000000"]\n5 -> 12 [label="> 6.15", color="#000000", fontcolor="#000000"]\n6 [label="\\"citric_acid\\"", shape="box", style="filled", fillcolor="#FFFFFFDD", fontcolor="#000000", color="#000000"]\n6 -> 13 [label="<= 0.259375", color="#000000", fontcolor="#000000"]\n6 -> 14 [label="> 0.259375", color="#000000", fontcolor="#000000"]\n7 [label=<<table border="0" cellspacing="0"> <tr><td port="port1" border="1" bgcolor="#87cefa" color="#000000"><FONT color="#000000"><b>prediction: 0 </b></FONT></td></tr><tr><td port="port0" border="1" align="left" color="#000000"><FONT color="#000000">prob(0): 0.7</FONT></td></tr><tr><td port="port1" border="1" align="left" color="#000000"><FONT color="#000000">prob(1): 0.3</FONT></td></tr></table>>, fillcolor="#FFFFFFDD", fontcolor="#000000", shape="none", color="#000000"]\n8 [label=<<table border="0" cellspacing="0"> <tr><td port="port1" border="1" bgcolor="#87cefa" color="#000000"><FONT color="#000000"><b>prediction: 0 </b></FONT></td></tr><tr><td port="port0" border="1" align="left" color="#000000"><FONT color="#000000">prob(0): 0.9</FONT></td></tr><tr><td port="port1" border="1" align="left" color="#000000"><FONT color="#000000">prob(1): 0.1</FONT></td></tr></table>>, fillcolor="#FFFFFFDD", fontcolor="#000000", shape="none", color="#000000"]\n9 [label=<<table border="0" cellspacing="0"> <tr><td port="port1" border="1" bgcolor="#efc5b5" color="#000000"><FONT color="#000000"><b>prediction: 1 </b></FONT></td></tr><tr><td port="port0" border="1" align="left" color="#000000"><FONT color="#000000">prob(0): 0.47</FONT></td></tr><tr><td port="port1" border="1" align="left" color="#000000"><FONT color="#000000">prob(1): 0.53</FONT></td></tr></table>>, fillcolor="#FFFFFFDD", fontcolor="#000000", shape="none", color="#000000"]\n10 [label=<<table border="0" cellspacing="0"> <tr><td port="port1" border="1" bgcolor="#87cefa" color="#000000"><FONT color="#000000"><b>prediction: 0 </b></FONT></td></tr><tr><td port="port0" border="1" align="left" color="#000000"><FONT color="#000000">prob(0): 0.74</FONT></td></tr><tr><td port="port1" border="1" align="left" color="#000000"><FONT color="#000000">prob(1): 0.26</FONT></td></tr></table>>, fillcolor="#FFFFFFDD", fontcolor="#000000", shape="none", color="#000000"]\n11 [label=<<table border="0" cellspacing="0"> <tr><td port="port1" border="1" bgcolor="#87cefa" color="#000000"><FONT color="#000000"><b>prediction: 0 </b></FONT></td></tr><tr><td port="port0" border="1" align="left" color="#000000"><FONT color="#000000">prob(0): 0.91</FONT></td></tr><tr><td port="port1" border="1" align="left" color="#000000"><FONT color="#000000">prob(1): 0.09</FONT></td></tr></table>>, fillcolor="#FFFFFFDD", fontcolor="#000000", shape="none", color="#000000"]\n12 [label=<<table border="0" cellspacing="0"> <tr><td port="port1" border="1" bgcolor="#87cefa" color="#000000"><FONT color="#000000"><b>prediction: 0 </b></FONT></td></tr><tr><td port="port0" border="1" align="left" color="#000000"><FONT color="#000000">prob(0): 0.72</FONT></td></tr><tr><td port="port1" border="1" align="left" color="#000000"><FONT color="#000000">prob(1): 0.28</FONT></td></tr></table>>, fillcolor="#FFFFFFDD", fontcolor="#000000", shape="none", color="#000000"]\n13 [label=<<table border="0" cellspacing="0"> <tr><td port="port1" border="1" bgcolor="#87cefa" color="#000000"><FONT color="#000000"><b>prediction: 0 </b></FONT></td></tr><tr><td port="port0" border="1" align="left" color="#000000"><FONT color="#000000">prob(0): 0.96</FONT></td></tr><tr><td port="port1" border="1" align="left" color="#000000"><FONT color="#000000">prob(1): 0.04</FONT></td></tr></table>>, fillcolor="#FFFFFFDD", fontcolor="#000000", shape="none", color="#000000"]\n14 [label=<<table border="0" cellspacing="0"> <tr><td port="port1" border="1" bgcolor="#87cefa" color="#000000"><FONT color="#000000"><b>prediction: 0 </b></FONT></td></tr><tr><td port="port0" border="1" align="left" color="#000000"><FONT color="#000000">prob(0): 0.86</FONT></td></tr><tr><td port="port1" border="1" align="left" color="#000000"><FONT color="#000000">prob(1): 0.14</FONT></td></tr></table>>, fillcolor="#FFFFFFDD", fontcolor="#000000", shape="none", color="#000000"]\n}'
This string can then be copied into a DOT file which can beparsed by graphviz.
Contour plot is another useful plot that can be produced for models with two predictors.
model.contour()
Important
Machine learning models with two predictors can usually benefit from their own contour plot. This visual representation aids in exploring predictions and gaining a deeper understanding of how these models perform in different scenarios. Please refer to Contour Plot for more examples.
Parameter Modification
In order to see the parameters:
model.get_params() Out[6]: {'n_estimators': 10, 'max_features': 'auto', 'max_leaf_nodes': 32, 'sample': 0.5, 'max_depth': 3, 'min_samples_leaf': 5, 'min_info_gain': 0.0, 'nbins': 32}
And to manually change some of the parameters:
model.set_params({'max_depth': 5})
Model Register
In order to register the model for tracking and versioning:
model.register("model_v1")
Please refer to /notebooks/ml/model_tracking_versioning/index.ipynb for more details on model tracking and versioning.
Model Exporting
To Memmodel
model.to_memmodel()
Note
MemModelobjects serve as in-memory representations of machine learning models. They can be used for both in-database and in-memory prediction tasks. These objects can be pickled in the same way that you would pickle ascikit-learnmodel.The following methods for exporting the model use
MemModel, and it is recommended to useMemModeldirectly.To SQL
You can get the SQL code by:
model.to_sql() Out[8]: '(CASE WHEN ((CASE WHEN "density" < 0.992198 THEN (CASE WHEN "residual_sugar" < 1.56875 THEN (CASE WHEN "density" < 0.991474 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "chlorides" < 0.046625 THEN 1.0 ELSE 0.0 END) END) ELSE (CASE WHEN "volatile_acidity" < 0.220625 THEN (CASE WHEN "fixed_acidity" < 6.15 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "citric_acid" < 0.259375 THEN 0.0 ELSE 0.0 END) END) END) + (CASE WHEN "chlorides" < 0.046625 THEN (CASE WHEN "density" < 0.992923 THEN (CASE WHEN "volatile_acidity" < 0.314375 THEN 0.0 ELSE 1.0 END) ELSE (CASE WHEN "volatile_acidity" < 0.220625 THEN 0.0 ELSE 0.0 END) END) ELSE (CASE WHEN "residual_sugar" < 12.225 THEN (CASE WHEN "citric_acid" < 0.31125 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "fixed_acidity" < 6.9 THEN 0.0 ELSE 0.0 END) END) END) + (CASE WHEN "density" < 0.991474 THEN (CASE WHEN "residual_sugar" < 1.56875 THEN (CASE WHEN "density" < 0.988578 THEN 1.0 ELSE 0.0 END) ELSE (CASE WHEN "citric_acid" < 0.415 THEN 1.0 ELSE 0.0 END) END) ELSE (CASE WHEN "density" < 0.993647 THEN (CASE WHEN "fixed_acidity" < 6.15 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "fixed_acidity" < 9.525 THEN 0.0 ELSE 0.0 END) END) END) + (CASE WHEN "density" < 0.992198 THEN (CASE WHEN "residual_sugar" < 1.56875 THEN (CASE WHEN "citric_acid" < 0.155625 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "residual_sugar" < 3.50625 THEN 0.0 ELSE 1.0 END) END) ELSE (CASE WHEN "volatile_acidity" < 0.220625 THEN (CASE WHEN "fixed_acidity" < 6.525 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "citric_acid" < 0.259375 THEN 0.0 ELSE 0.0 END) END) END) + (CASE WHEN "citric_acid" < 0.259375 THEN (CASE WHEN "chlorides" < 0.046625 THEN (CASE WHEN "density" < 0.99075 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "density" < 0.996543 THEN 0.0 ELSE 0.0 END) END) ELSE (CASE WHEN "chlorides" < 0.046625 THEN (CASE WHEN "density" < 0.992198 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "fixed_acidity" < 8.775 THEN 0.0 ELSE 0.0 END) END) END) + (CASE WHEN "chlorides" < 0.046625 THEN (CASE WHEN "residual_sugar" < 6.4125 THEN (CASE WHEN "density" < 0.991474 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "citric_acid" < 0.259375 THEN 0.0 ELSE 0.0 END) END) ELSE (CASE WHEN "citric_acid" < 0.259375 THEN (CASE WHEN "residual_sugar" < 2.5375 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "volatile_acidity" < 0.408125 THEN 0.0 ELSE 0.0 END) END) END) + (CASE WHEN "density" < 0.992198 THEN (CASE WHEN "density" < 0.991474 THEN (CASE WHEN "citric_acid" < 0.31125 THEN 1.0 ELSE 0.0 END) ELSE (CASE WHEN "residual_sugar" < 2.5375 THEN 0.0 ELSE 1.0 END) END) ELSE (CASE WHEN "volatile_acidity" < 0.220625 THEN (CASE WHEN "fixed_acidity" < 6.525 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "chlorides" < 0.027813 THEN 0.0 ELSE 0.0 END) END) END) + (CASE WHEN "chlorides" < 0.046625 THEN (CASE WHEN "density" < 0.992923 THEN (CASE WHEN "density" < 0.99075 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "volatile_acidity" < 0.220625 THEN 0.0 ELSE 0.0 END) END) ELSE (CASE WHEN "citric_acid" < 0.259375 THEN (CASE WHEN "fixed_acidity" < 5.4 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "volatile_acidity" < 0.17375 THEN 0.0 ELSE 0.0 END) END) END) + (CASE WHEN "volatile_acidity" < 0.501875 THEN (CASE WHEN "chlorides" < 0.046625 THEN (CASE WHEN "chlorides" < 0.027813 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "fixed_acidity" < 8.775 THEN 0.0 ELSE 0.0 END) END) ELSE (CASE WHEN "chlorides" < 0.065437 THEN (CASE WHEN "volatile_acidity" < 0.595625 THEN 0.0 ELSE 0.0 END) ELSE 0.0 END) END) + (CASE WHEN "chlorides" < 0.046625 THEN (CASE WHEN "residual_sugar" < 9.31875 THEN (CASE WHEN "density" < 0.992198 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "density" < 0.995819 THEN 0.0 ELSE 0.0 END) END) ELSE (CASE WHEN "volatile_acidity" < 0.220625 THEN (CASE WHEN "citric_acid" < 0.466875 THEN 0.0 ELSE 0.0 END) ELSE (CASE WHEN "citric_acid" < 0.31125 THEN 0.0 ELSE 0.0 END) END) END)) / 10 > 0.5 THEN 1 ELSE 0 END)'
To Python
To obtain the prediction function in Python syntax, use the following code:
X = [[4.2, 0.17, 0.36, 1.8, 0.029, 0.9899]] model.to_python()(X) Out[10]: array([0])
Hint
The
to_python()method is used to retrieve predictions, probabilities, or cluster distances. For specific details on how to use this method for different model types, refer to the relevant documentation for each model.- __init__(name: str = None, overwrite_model: bool = False, n_estimators: int = 10, max_features: Literal['auto', 'max'] | int = 'auto', max_leaf_nodes: Annotated[int | float | Decimal, 'Python Numbers'] = 1000000000.0, sample: float = 0.632, max_depth: int = 5, min_samples_leaf: int = 1, min_info_gain: Annotated[int | float | Decimal, 'Python Numbers'] = 0.0, nbins: int = 32) None
Must be overridden in the child class
Methods
__init__([name, overwrite_model, ...])Must be overridden in the child class
classification_report([metrics, cutoff, ...])Computes a classification report using multiple model evaluation metrics (
auc,accuracy,f1...).confusion_matrix([pos_label, cutoff])Computes the model confusion matrix.
contour([pos_label, nbins, chart])Draws the model's contour plot.
cutoff_curve([pos_label, nbins, show, chart])Draws the model Cutoff curve.
deploySQL([X, pos_label, cutoff, allSQL])Returns the SQL code needed to deploy the model.
does_model_exists(name[, raise_error, ...])Checks whether the model is stored in the Vertica database.
drop()Drops the model from the Vertica database.
export_models(name, path[, kind])Exports machine learning models.
features_importance([tree_id, show, chart])Computes the model's features importance.
fit(input_relation, X, y[, test_relation, ...])Trains the model.
get_attributes([attr_name])Returns the model attributes.
get_match_index(x, col_list[, str_check])Returns the matching index.
Returns the parameters of the model.
get_plotting_lib([class_name, chart, ...])Returns the first available library (Plotly, Matplotlib, or Highcharts) to draw a specific graphic.
get_score([tree_id])Returns the feature importance metrics for the input tree.
get_tree([tree_id])Returns a table with all the input tree information.
get_vertica_attributes([attr_name])Returns the model Vertica attributes.
import_models(path[, schema, kind])Imports machine learning models.
lift_chart([pos_label, nbins, show, chart])Draws the model Lift Chart.
plot([max_nb_points, chart])Draws the model.
plot_tree([tree_id, pic_path])Draws the input tree.
prc_curve([pos_label, nbins, show, chart])Draws the model PRC curve.
predict(vdf[, X, name, cutoff, inplace])Predicts using the input relation.
predict_proba(vdf[, X, name, pos_label, inplace])Returns the model's probabilities using the input relation.
register(registered_name[, raise_error])Registers the model and adds it to in-DB Model versioning environment with a status of 'under_review'.
report([metrics, cutoff, labels, nbins])Computes a classification report using multiple model evaluation metrics (
auc,accuracy,f1...).roc_curve([pos_label, nbins, show, chart])Draws the model ROC curve.
score([metric, average, pos_label, cutoff, ...])Computes the model score.
set_params([parameters])Sets the parameters of the model.
Summarizes the model.
to_binary(path)Exports the model to the Vertica Binary format.
to_graphviz([tree_id, classes_color, ...])Returns the code for a Graphviz tree.
Converts the model to an InMemory object that can be used for different types of predictions.
to_pmml(path)Exports the model to PMML.
to_python([return_proba, ...])Returns the Python function needed for in-memory scoring without using built-in Vertica functions.
to_sql([X, return_proba, ...])Returns the SQL code needed to deploy the model without using built-in Vertica functions.
to_tf(path)Exports the model to the Frozen Graph format (TensorFlow).
Attributes